Automated Lead Enrichment Workflow: The Complete Guide
Discover how to design a reliable automated lead enrichment workflow that transforms incomplete lead records into useful, validated CRM data. Compare no-code automation, self-hosted n8n, and custom-coded pipelines, with practical API examples, data-merging rules, testing strategies, and production best practices.
- 1.Automated Lead Enrichment Workflow: The Complete Guide
Automated Lead Enrichment Workflow: The Complete Guide
A new lead enters your CRM with a name, an email address and little else. Your sales team still needs to discover the person's role, identify their company, check whether the account fits your ideal customer profile and determine who should follow up.
When this process happens manually, sales representatives spend time researching records instead of engaging prospects. When it happens automatically without adequate controls, the CRM can fill up with incorrect company matches, stale contact details and duplicate records.
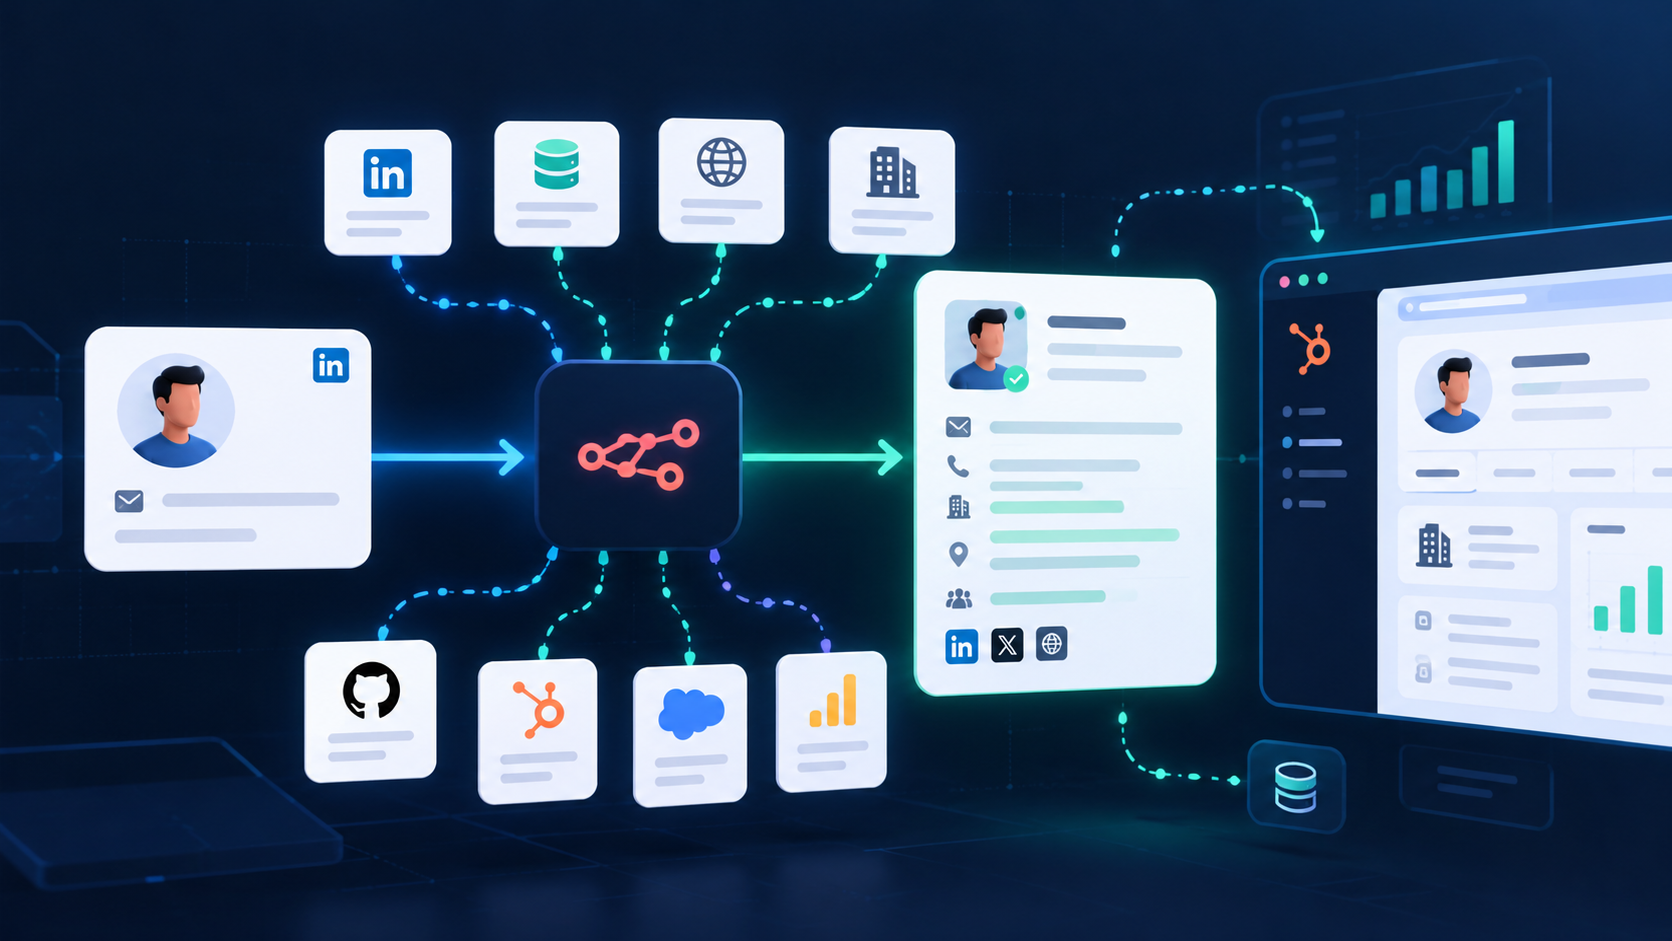
An automated lead enrichment workflow addresses both problems. It collects existing lead information, retrieves relevant additional data, validates the results, merges trustworthy values into a consistent record and sends the updated information to the systems that need it.
The challenge is designing a workflow that does more than successfully call an API. It must also handle missing information, conflicting sources, provider outages, rate limits, duplicate events and changes to existing CRM records.
This guide explains how to design and implement a complete lead enrichment pipeline using no-code automation, self-hosted n8n or a custom-coded application. You will also learn how to select providers, protect personal data, test the workflow and measure whether it is producing useful results.
Table of Contents
- What is an automated lead enrichment workflow?
- Lead generation vs. lead enrichment vs. lead scoring
- Benefits and use cases
- End-to-end workflow architecture
- How to build a no-code workflow
- How to build a self-hosted workflow with n8n
- How to build a lead enrichment pipeline with code
- Comparing implementation approaches
- Choosing providers and designing enrichment waterfalls
- Reliability, retries and failure handling
- Data quality, privacy and security
- Testing and success metrics
- Cost considerations
- Common mistakes and troubleshooting
- Implementation checklist
- Frequently asked questions
1. What Is an Automated Lead Enrichment Workflow?
An automated lead enrichment workflow is a repeatable process that uses software integrations, APIs and predefined rules to add relevant information to existing lead records without requiring someone to research and update every record manually.
A lead may initially contain only a name and business email. Depending on the available sources and permissions, enrichment could add:
- Job title and professional role
- Company name and website
- Industry and company size
- Headquarters or business location
- Department or seniority
- Business email verification status
- Company technology information, where available and relevant
- Data source, last-checked timestamp and confidence information
Not every provider returns every field. Coverage depends on the input data, provider dataset, geography, matching rules, subscription and applicable permissions.
A well-designed workflow also records what it could not establish. An unsuccessful lookup should not automatically be treated as evidence that a person or company does not exist.
Why automate lead enrichment?
Consider a team that receives hundreds of leads through website forms, webinar registrations, referrals and partner integrations.
Without automation, someone may need to copy the information into a CRM, search for company details, update missing fields and assign an owner. Repeating those steps creates delays and makes data handling inconsistent.
An automated workflow can perform these operations using the same rules for every eligible record.
Its value comes from more than saving manual work. It can also help teams:
- Apply consistent qualification rules.
- Reduce duplicate records and unnecessary provider lookups.
- Route leads using company and contact attributes.
- Track where CRM values came from.
- Identify records that need human review.
- Refresh selected data on a defined schedule.
Automation does not guarantee accurate data. It makes the process more repeatable, measurable and easier to improve.
2. Lead Generation vs. Lead Enrichment vs. Lead Scoring
These activities are related, but they solve different problems.
| Activity | Main purpose | Example |
|---|---|---|
| Lead generation | Identify or attract potential customers | Capture a demo request |
| Lead enrichment | Add relevant context to an existing lead | Match the contact to a company and retrieve its industry |
| Lead scoring | Estimate how well a lead fits defined qualification criteria | Assign points for target industry, company size and seniority |
| Lead routing | Decide where a lead should go next | Assign a qualified lead to the appropriate sales representative |
A complete system can combine all four processes, but they should remain logically distinct.
For example, a form submission can trigger enrichment. The enriched record can then enter a scoring process, followed by routing if it meets the team's qualification rules.
Keeping these stages separate makes the workflow easier to debug. If a lead is routed incorrectly, you can determine whether the issue originated in data matching, enrichment, scoring or assignment.
3. Benefits and Practical Use Cases
3.1 Inbound lead qualification
A prospect submits a demo request containing a work email and company name. The workflow identifies the existing CRM record, retrieves available firmographic information, evaluates the lead against defined criteria and updates the record.
A sales representative receives useful context without having to research every field manually.
3.2 Outbound prospecting
A sales team imports a list of prospective contacts. The workflow normalizes company domains, checks for existing records, enriches missing fields and marks incomplete matches for review.
This makes large-list preparation more consistent, although it does not guarantee that every contact can be matched or verified.
3.3 CRM data maintenance
A company may want to revisit selected records periodically to identify missing or outdated job titles, company information or verification statuses.
Rather than refreshing every field indiscriminately, the workflow can prioritize records based on business importance, field freshness and the cost of a lookup.
3.4 Account-based marketing
A team targeting specific companies can enrich account records with available company-level attributes and associate relevant contacts with those accounts.
These attributes can support segmentation and account prioritization. They should not be interpreted as proof of buying intent unless the system has an appropriate, defensible signal.
3.5 Lead routing and personalization
Once the required fields are available, business rules can determine the appropriate sales territory, account owner or follow-up queue.
AI may also summarize sourced information for a representative. However, generated summaries should not silently convert assumptions into verified facts.
4. End-to-End Lead Enrichment Workflow Architecture
A reliable system separates data collection, enrichment, decision-making and storage.
The following architecture is suitable for a typical B2B implementation. It is a recommended design, not a requirement to use a particular software stack.
Step 1: Capture the lead
A trigger starts the workflow when a new lead arrives or an existing record requires enrichment.
Possible triggers include:
- A form submission
- A CRM webhook
- A scheduled batch job
- A new row in a spreadsheet
- An internal application event
- A message placed on a queue
For reliable processing, retain the original event ID or another stable identifier. This helps distinguish a genuinely new lead from a repeated delivery of the same event.
Step 2: Validate and normalize the input
Before spending money on enrichment, verify that the record contains enough information to make a useful lookup.
Examples of normalization include:
- Trimming whitespace from names and email addresses.
- Lowercasing email addresses for matching and comparison.
- Extracting a domain from a valid email address.
- Normalizing website URLs.
- Converting country names and other controlled fields to a consistent format.
- Preserving the original input separately when it is needed for auditability.
Normalization should not destroy meaningful information. Names, for example, can contain punctuation, accents and different capitalization conventions.
An invalid or incomplete record should enter a defined rejection or review path rather than automatically continuing through every provider.
Step 3: Find existing records and deduplicate
Before creating a new CRM contact, search for a matching record using appropriate identifiers.
A practical matching order might be:
- Existing CRM contact ID, when supplied by a trusted internal system.
- A normalized email address, when appropriate for the system.
- A provider-supported professional profile identifier.
- A company domain combined with additional identifying attributes.
- Manual review when the match is ambiguous.
A company domain alone is generally insufficient to identify a person. Multiple employees can share the same domain, and different organizations can have similar names.
Do not merge two people simply because they have the same name or work for the same company.
Step 4: Select the provider and requested fields
Determine which fields are missing, stale or explicitly approved for refresh.
For example, if a CRM record already contains a verified company website and current industry value, there may be no reason to pay a provider to retrieve them again.
The workflow should pass only the inputs and request only the fields necessary for the intended task, subject to the provider's API and contractual requirements.
Step 5: Validate the enrichment result
A successful HTTP response does not necessarily mean that the correct person or company was matched.
Validate:
- Whether the provider returned a match.
- Whether the match is sufficiently specific.
- Whether returned fields have the expected types.
- Whether required values are missing.
- Whether the source and timestamp are recorded.
- Whether the response contains a warning or ambiguous result.
Reject or flag questionable results rather than forcing them into the CRM.
Step 6: Merge fields using explicit rules
For every field, define which sources are allowed to supply it and when an incoming value can replace an existing value.
The workflow should preserve provenance: which source supplied the value, when it was retrieved and whether it was verified.
Step 7: Update the CRM or database
Use an upsert or equivalent controlled update process wherever supported. An upsert updates an existing record when a match is found and creates one when no suitable record exists.
The actual operation depends on the CRM's API and data model.
Update only approved fields. A newly enriched record should not accidentally overwrite owner assignments, consent records, sales notes or other fields managed by different processes.
Step 8: Score, route and monitor
Once the record passes the required checks, the workflow can calculate a lead score, assign an owner or notify a sales channel.
Record the final outcome, including partial success and failure. A record with three successfully enriched fields and two missing fields is not necessarily a complete failure; the workflow should report that distinction.
5. How to Build a No-Code Lead Enrichment Workflow
A no-code approach is a practical starting point for teams that need to connect forms, enrichment services and CRMs without maintaining a custom application.
Tools such as Zapier and Make can connect supported applications, while many enrichment providers also offer native integrations.
Components you need
- A lead source, such as a form or CRM.
- An automation platform.
- An enrichment provider with suitable integrations.
- A destination CRM or database.
- Conditional steps for validation and duplicate handling.
- A way to record failures and review incomplete results.
Step-by-step implementation
Step 1: Choose the trigger.
Create a workflow that starts when a new lead is submitted or a record is marked for enrichment.
Avoid triggering enrichment every time an unrelated CRM field changes. Otherwise, your workflow may repeatedly enrich the same lead.
Step 2: Normalize the incoming data.
Use the platform's built-in formatting or transformation steps to normalize emails, domains and other matching fields.
Add a condition that prevents obviously invalid inputs from reaching the enrichment provider.
Step 3: Check for an existing record.
Search the destination CRM before creating a contact. If a match exists, retain its record identifier and continue with an update path.
If the search returns several possible matches, route the record for review instead of guessing.
Step 4: Call the enrichment service.
Use a supported native integration when it provides the required fields and matching behavior. If not, use an HTTP request or webhook step, provided the platform and provider support the necessary authentication and request format.
Keep API credentials in the platform's credential manager rather than embedding them in ordinary text fields.
Step 5: Apply conditional merge rules.
Map provider values to CRM properties. Configure the workflow to fill missing fields or refresh approved stale values without overwriting trusted information indiscriminately.
Step 6: Handle unsuccessful results.
Create separate branches for:
- Successful, sufficiently confident matches.
- No match found.
- Partial enrichment.
- Rate-limit or temporary service errors.
- Invalid requests or authentication failures.
A failure branch should log enough information for diagnosis without exposing unnecessary personal data or secrets.
Step 7: Update the CRM and notify the team.
Write the approved fields, record the enrichment status and notify the appropriate owner if human review is required.
Advantages
- Fast initial implementation.
- Less code to maintain.
- Accessible to operations and marketing teams.
- Convenient integrations with common business applications.
Limitations and operational considerations
Complex field-merging rules, large batches, specialized authentication and intricate recovery paths may become difficult to manage in a visual workflow.
Task-based pricing, execution limits and provider API charges also affect total cost. Review how the platform handles credentials, logs, retries, concurrency and execution history before moving sensitive or high-volume data through it.
When to choose another approach
Consider n8n or custom code if you need more control over deployment, complex transformations, custom matching logic, specialized testing or high-volume processing.
For a focused implementation tutorial, see the planned follow-up article: How to Build a No-Code Lead Enrichment Workflow. Add its internal link after publication.
6. How to Build a Self-Hosted Lead Enrichment Workflow with n8n
n8n is a workflow automation platform that supports visual workflow design alongside API requests and custom transformation logic. A self-hosted deployment gives an organization control over its deployment environment, but it also makes that organization responsible for operational security and maintenance.
Self-hosting does not automatically make a workflow private, secure or compliant. Configuration, infrastructure, credentials, logging and external provider transfers still matter.
Suggested node sequence
A typical workflow can use these logical steps:
- Trigger: Webhook, supported CRM event or schedule.
- Edit Fields or equivalent: Normalize and prepare the input.
- CRM lookup: Find an existing contact or account.
- IF: Check whether the record is eligible for enrichment.
- HTTP Request: Call the selected provider.
- Code or transformation step: Validate and map the response.
- Merge or conditional logic: Apply field-level precedence rules.
- CRM node or HTTP Request: Update the existing record or create a new one.
- Error-handling path: Record failures and route records for retry or review.
Exact node names, options and API requirements depend on the n8n version and connected applications.
Implementation steps
Step 1: Create the trigger.
Start with a webhook or supported event trigger. During development, use a small test payload rather than immediately processing your entire CRM.
A useful input might contain an email address, company domain and internal event ID.
Step 2: Normalize the data.
Use built-in transformation nodes or a Code node to create a consistent internal record. Keep a stable internal identifier so that later steps can update the correct lead.
Step 3: Search before writing.
Use the CRM's supported search or lookup operation. Store the matched record ID and branch appropriately for new, existing and ambiguous records.
Step 4: Configure the HTTP Request node.
Select the method, URL, authentication method, headers and body required by the actual provider documentation.
Store credentials in n8n's credential facilities. Do not put API keys directly in a workflow's ordinary text fields or include them in log messages.
Step 5: Validate the response.
Check the response structure, match status and field values before mapping them into the normalized record. Do not assume that every successful request returns the same fields.
Step 6: Merge and update.
Apply the same field-level precedence rules used in a coded implementation. Use the CRM record ID or another appropriate stable identifier to perform the update.
Step 7: Add retries and error handling.
n8n documents batching and Retry on Fail as options for handling rate limits and failed HTTP requests. The appropriate batch size, retry count and delay depend on the provider's limits and failure behavior. See the n8n HTTP Request troubleshooting documentation.
A retry should not create duplicate contacts or repeat a non-idempotent operation without safeguards.
Self-hosting checklist
- Restrict access to the n8n editor and webhook endpoints.
- Use HTTPS for externally accessible endpoints.
- Keep n8n, its host and dependencies updated.
- Store encryption keys and credentials securely.
- Configure backups and test restoration.
- Review execution-data retention and log exposure.
- Monitor failed executions, queue health and resource usage.
- Limit access to workflows that process personal information.
When n8n is the right choice
Choose n8n when visual workflow design is useful but you also need HTTP integrations, custom transformations, branching and deployment control.
A self-hosted workflow is not necessarily cheaper than a managed platform. Infrastructure, upgrades, troubleshooting, backups and monitoring are part of its total cost.
The planned follow-up article, How to Build a Self-Hosted Lead Enrichment Workflow with n8n, can provide a dedicated node-by-node tutorial.
7. How to Build a Lead Enrichment Pipeline with Code
A custom-coded pipeline is appropriate when the workflow requires precise control over matching, provider selection, field provenance, concurrency, testing or operational behavior.
A useful implementation separates business rules from provider-specific request logic. This makes it possible to change enrichment providers without rewriting the entire pipeline.
Recommended components
- Ingestion: Accepts webhooks, events or batch records.
- Normalization: Converts input into a stable internal schema.
- Identity resolution: Finds existing contacts and accounts.
- Provider adapters: Call each enrichment service.
- Merge engine: Applies field-level precedence and freshness rules.
- Persistence: Stores the final record and its audit metadata.
- Queue or job runner: Supports asynchronous processing and recovery.
- Observability: Captures outcomes, latency, costs and failures.
For a small application, these components can exist in one service. A distributed architecture is not necessary until the requirements justify it.
Example normalized lead record
The following JSON is an illustrative internal schema. The field names and values are design examples, not a provider's API response.
{
  "lead_id": "lead_10042",
  "identity": {
    "email": "alex@example.com",
    "company_domain": "example.com"
  },
  "contact": {
    "first_name": "Alex",
    "last_name": "Morgan",
    "job_title": null
  },
  "company": {
    "name": "Example Systems",
    "industry": null,
    "employee_range": null
  },
  "enrichment": {
    "status": "pending",
    "attempt_count": 0,
    "last_attempt_at": null
  },
  "field_metadata": {
    "contact.job_title": {
      "source": null,
      "retrieved_at": null,
      "verified": false
    },
    "company.industry": {
      "source": null,
      "retrieved_at": null,
      "verified": false
    }
  }
}
The verified property should mean that a defined verification procedure has actually been performed. It must not simply mean that a provider returned a value.
For a more mature system, consider adding:
- A stable provider match identifier.
- A source-specific record ID.
- A timestamp for each field's last successful refresh.
- A match confidence value with a documented interpretation.
- An explicit distinction between sourced, inferred and manually confirmed values.
- A processing version for the workflow or merge rules.
- A data-retention or deletion status where appropriate.
Field mapping and merge precedence
Do not use a single global rule such as "the newest value always wins." The best source can differ by field.
For example, the CRM may be the authoritative source for account ownership, a verified internal submission may be authoritative for the contact's stated details, and an enrichment provider may be useful for company headcount.
Define rules before implementation.
| Field | Example preferred source | Update rule |
|---|---|---|
| CRM record ID | CRM | Never replace with provider data |
| Account owner | CRM or assignment system | Update only through approved routing logic |
| Contact's stated name | Trusted first-party input | Preserve unless an authorized correction is made |
| Company industry | Approved company-data source | Refresh if missing or sufficiently stale |
| Employee range | Approved provider | Replace only under the field's freshness and source rules |
| Email verification status | Verification provider | Store result with provider and timestamp |
| AI-generated role category | Internal classification process | Store separately from the sourced job title |
A possible field-level merge policy is:
- Preserve a valid, trusted existing value unless an approved refresh rule applies.
- Accept a provider value only when the match and field pass validation.
- Compare source priority, freshness and verification status.
- Preserve the winning value's provenance.
- Record conflicting candidates when they cannot be resolved safely.
- Leave a field empty or flag it for review when no acceptable value exists.
A simplified merge decision can be represented as:
if incoming_value is invalid:
    keep existing value
elif existing_value is missing:
    accept incoming value if match is acceptable
elif refresh policy permits replacement:
    compare source quality, freshness, and verification
    update only if the replacement rule passes
else:
    preserve existing value
The important point is that merge precedence is a business rule, not an accidental consequence of whichever API response arrived last.
Practical enrichment API example
The Coresignal B2B lead enrichment guide documents a company-enrichment request pattern using its Company Data API:
curl -X GET \
  'https://api.coresignal.com/cdapi/v2/{entity}/enrich?website={URL}&fields={field_name}' \
  -H 'accept: application/json' \
  -H 'apikey: YOUR_API_KEY'
This is a request template, not a copy-and-run request. Replace the entity path, website parameter and field names with the values supported by the specific endpoint and current API documentation. URL-encode parameter values and use a secure method to supply the API key.
The example illustrates the request structure:
- The endpoint identifies the enrichment resource.
- The website parameter supplies a company-matching input.
- The fields parameter requests selected output fields.
- The API-key header supplies authentication.
For a production implementation, confirm the current endpoint, required parameters, supported field names, response schema, error codes, limits and billing behavior in the provider's official documentation.
The exact response depends on the endpoint and match. Do not hard-code a hypothetical provider response into production code.
Instead, transform the actual response into your own normalized schema:
{
  "lead_id": "lead_10042",
  "enrichment_status": "partial",
  "matched_entity": "company",
  "fields_updated": [
    "company.industry"
  ],
  "fields_missing": [
    "company.employee_range"
  ],
  "review_required": false
}
This is an illustrative internal processing result, not a Coresignal API response.
Idempotency and duplicate prevention
An operation is idempotent when repeating the same operation under the same conditions produces the same intended final state rather than creating additional side effects.
For example, processing the same lead event twice should not create two CRM contacts.
A common design is to derive a stable processing key from an internal event ID or an appropriate combination of record ID, enrichment version and requested operation.
Store the processing state and use database constraints or equivalent safeguards where available. For updates, prefer stable record identifiers and operations that are safe to repeat.
Remember that checking for an existing record and then creating a new one can still produce duplicates when two workers execute simultaneously. Concurrency controls or uniqueness constraints may be needed.
Scaling the pipeline
At higher volumes, introduce a queue or durable job store so that ingestion is separated from enrichment.
This makes it easier to:
- Control concurrency.
- Respect provider-specific rate limits.
- Retry transient failures.
- Resume interrupted jobs.
- Track individual record outcomes.
- Prevent one provider outage from blocking all incoming leads.
Do not introduce distributed infrastructure just because it sounds more sophisticated. Start with the simplest architecture that meets your volume, reliability and operational requirements.
8. Comparing No-Code, n8n and Full-Stack Implementations
There is no universally best approach. The right choice depends on the complexity of your business rules, technical resources and expected workload.
| Dimension | No-code automation | Self-hosted n8n | Custom code |
|---|---|---|---|
| Initial setup | Usually fastest | Moderate | Usually highest |
| Coding required | Minimal | Optional to moderate | Significant |
| Custom logic | Depends on platform | Flexible | Highly flexible |
| Deployment control | Platform-dependent | Greater control | Depends on architecture |
| Maintenance | Platform and workflow maintenance | Infrastructure plus workflow maintenance | Application and infrastructure maintenance |
| Complex merging | Can become cumbersome | Good for moderate complexity | Best suited to highly specialized rules |
| Testing | Platform-dependent | Workflow and integration tests | Full testing flexibility |
| Scaling | Depends on platform limits | Depends on deployment and configuration | Depends on architecture and implementation |
| Best fit | Standard integrations and quick validation | API-heavy visual workflows | Specialized, high-control systems |
Choose no-code when
- Your use case is straightforward.
- Native integrations cover most requirements.
- The workflow is maintained by operations or marketing staff.
- You want to validate the process before investing in engineering.
Choose self-hosted n8n when
- You want visual workflow management.
- Custom API requests and transformations are necessary.
- You can operate and secure the deployment.
- You need more control than a basic connector-based workflow offers.
Choose custom code when
- Matching and merge rules are complex.
- You need strong automated testing and specialized observability.
- Your pipeline requires precise concurrency and recovery behavior.
- Your product or internal system needs a reusable enrichment service.
A hybrid architecture is also possible. For example, a coded service can handle identity resolution and merging while a workflow platform orchestrates notifications and downstream CRM actions.
9. Choosing Enrichment Providers and Designing Waterfalls
A lead enrichment waterfall calls multiple providers in a defined sequence when earlier sources fail to supply acceptable data.
For example:
- Check first-party CRM and account data.
- Query the primary enrichment provider.
- Query a secondary provider for required missing fields.
- Verify selected contact details with a suitable verification service.
- Send unresolved records for review.
The sequence should be based on the value of the fields being retrieved, match quality, provider terms, cost and latency. More providers do not automatically produce better data.
How to evaluate a provider
Assess the following:
- Coverage: Does the provider support your target geographies, industries and company types?
- Match quality: Can you distinguish a reliable match from an ambiguous one?
- Field availability: Does it return the specific attributes you need?
- Freshness: Does it expose timestamps or other useful freshness information?
- Verification: What does each verification status actually establish?
- API reliability: What are the documented rate limits, timeouts and failure behaviors?
- Cost: Are charges based on requests, successful matches, credits or another unit?
- Integration effort: Does the provider offer the required API, native connector or webhook?
- Data rights: Are your intended use, retention and downstream processing permitted under the provider's terms and applicable laws?
Test candidates against a representative sample of your actual leads before committing to a provider.
Design a field-aware waterfall
A company enrichment provider may be suitable for industry and employee range, while a separate verification service may be more appropriate for checking an email address.
Instead of asking every provider for every possible field, identify what is still missing after each step.
For example:
Required fields:
- Company industry
- Employee range
- Email verification status

Step 1: Check trusted internal records.
Step 2: Retrieve missing company attributes.
Step 3: Verify the email if required and permitted.
Step 4: Validate the results.
Step 5: Mark unresolved fields or send them for review.
Set a maximum number of provider attempts. Otherwise, a record with persistently missing data can repeatedly trigger costly lookups.
Track the contribution of each provider by field, not just the total number of responses it returns.
10. Reliability, Retries and Failure Handling
Production reliability requires more than a retry button.
Understand the failure type
| Failure | Typical response |
|---|---|
| Invalid input | Correct or reject the record |
| No match found | Mark as unmatched; optionally try an approved fallback |
| HTTP 400 | Inspect the request and correct the input or parameters |
| HTTP 401 or 403 | Check credentials and permissions |
| HTTP 429 | Respect rate-limit guidance and retry according to the provider's policy |
| HTTP 5xx | Retry selectively with backoff |
| Timeout | Retry cautiously; determine whether the request may already have succeeded |
| Invalid response schema | Quarantine the result and investigate |
| CRM write failure | Retry the write safely or queue it for recovery |
These are general HTTP troubleshooting guidelines. Actual provider behavior and error semantics must be checked against its documentation.
Use bounded retries with backoff
For transient failures, exponential backoff increases the delay between retries. Jitter adds randomness to reduce the chance that many workers retry simultaneously.
A simplified schedule might be:
Attempt 1: immediate
Attempt 2: after 1 second
Attempt 3: after 2 seconds
Attempt 4: after 4 seconds
These values are illustrative, not universal defaults. In production, set a retry limit, maximum delay and total deadline. Honor provider instructions such as Retry-After when applicable.
Do not keep retrying invalid requests or permanent authentication errors.
Prevent duplicate side effects
A timeout does not always mean that the remote system failed to process a request. The server may have completed the operation while the response was lost.
For operations that create records or trigger external actions, use provider-supported idempotency keys where available, stable identifiers, deduplication and post-timeout reconciliation.
If the provider does not support idempotency keys, design a safe lookup-and-reconcile process before retrying uncertain writes.
Add dead-letter handling
When a job exhausts its retries, move it into a durable failed-job queue or equivalent recovery mechanism.
Store a correlation ID, failure category, attempt count and safe diagnostic details. Avoid storing API secrets or unnecessary personal data in error records.
Make replay an intentional operation. Before reprocessing a job, confirm that it will not duplicate CRM records or trigger unwanted downstream actions.
Monitor the entire workflow
Useful monitoring signals include:
- Successful, partial and failed enrichment counts.
- No-match and ambiguous-match rates.
- API error rates and rate-limit responses.
- Queue age and processing latency.
- Duplicate prevention events.
- CRM write failures.
- Cost per successfully enriched lead.
- The proportion of records requiring manual review.
Monitoring should distinguish provider availability from actual data quality. An API can be healthy while returning a high proportion of unusable matches.
11. Data Quality, Privacy and Security
Enrichment often involves professional information associated with identifiable people. Treat it as a data-governance responsibility, not simply an API integration.
Preserve data provenance
For each enriched field, consider storing:
- The value.
- The source or provider.
- The retrieval timestamp.
- A verification status where applicable.
- A confidence score only when its meaning is documented.
- Whether the value was sourced, inferred or manually confirmed.
This information helps teams resolve conflicting values and identify records that may need refreshing.
Separate facts from inferences
Suppose an AI system infers that a job title belongs to a particular department.
The inferred department should be stored separately from the original job title. Do not write the inference into a field that represents a verified source value.
Similarly, a provider match score is not necessarily a probability that the match is correct. Interpret scores according to the provider's documented meaning.
Apply data minimization
Collect only fields needed for a defined business purpose. Restrict access to the systems and records that require it, and define how long data and execution logs should be retained.
The UK's Information Commissioner's Office outlines principles that include lawful and fair processing, purpose limitation, data minimization, accuracy, storage limitation and appropriate security. See its data protection principles.
Requirements differ by jurisdiction and context. Evaluate applicable privacy, marketing, data-broker and electronic communications rules with qualified counsel where necessary. No workflow design alone guarantees legal compliance.
Secure credentials and integrations
- Use managed credential storage or an appropriate secret manager.
- Apply least-privilege permissions.
- Keep production and development credentials separate.
- Avoid sending unnecessary personal information to AI services.
- Redact secrets and sensitive values from logs.
- Restrict workflow-editor and database access.
- Document retention and deletion procedures.
- Review provider terms, subprocessors and permitted uses.
- Ensure deletion or correction requests can propagate to relevant systems when required.
Self-hosting does not remove responsibilities associated with third-party providers or personal-data processing.
12. Testing and Measuring Success
A successful API call is not sufficient evidence that the workflow works correctly. Test the decisions that occur before and after the request.
Testing checklist
- Valid lead with all required input fields.
- Missing email or company identifier.
- Whitespace, capitalization and domain normalization.
- Existing CRM record.
- Duplicate event delivered more than once.
- Two concurrent jobs attempting to create the same contact.
- Provider returns no match.
- Provider returns only some requested fields.
- Provider returns conflicting values.
- Provider returns an ambiguous match.
- HTTP 429 or another temporary failure.
- HTTP 401 or 403 due to invalid credentials.
- Timeout after a potentially successful request.
- Malformed or unexpected response.
- CRM update failure.
- Retry limit exhausted.
- Manual-review and replay paths.
- Sensitive information is absent from logs.
- Deletion and retention behavior.
- Correct cost and outcome metrics are recorded.
Use synthetic or otherwise appropriately authorized test data. Avoid using real personal information unnecessarily in development.
Measure field completeness
Field completeness measures the proportion of required field opportunities that contain acceptable values.
Formula:
Completeness = (Number of required field values present and acceptable ÷ Total required field opportunities) × 100
For example, if 80 of 100 required field opportunities contain acceptable values, completeness is 80%.
Define what counts as an acceptable value before measuring. A non-empty but invalid email address should not count as complete.
Measure enrichment coverage
Coverage can be defined as the proportion of eligible leads for which at least one required enrichment outcome was obtained.
Coverage = (Eligible leads meeting the defined enrichment-success criterion ÷ Total eligible leads processed) × 100
The success criterion should be documented. For instance, a company match might count as coverage even when a phone number remains unavailable.
Measure accuracy
Accuracy requires an independent reference standard, such as a suitably sampled set of manually reviewed records or a trusted, authorized reference dataset.
Accuracy = (Reviewed enriched values confirmed correct ÷ Total enriched values reviewed) × 100
Report the sample size and sampling method. Accuracy measured on a small or biased sample may not represent the full pipeline.
For important fields, measure false matches separately. A confidently incorrect contact match can be more harmful than an unresolved record.
Measure cost per successfully enriched lead
Cost per successful enrichment = Total attributable enrichment cost ÷ Number of leads meeting the defined success criterion
Include provider charges, verification charges and relevant platform or infrastructure costs. State which costs are included so that comparisons remain meaningful.
Measure latency and reliability
Track the time from initial event receipt to the final accepted CRM update. Report percentiles, such as median and 95th-percentile latency, rather than relying only on the average.
Also track the proportion of eligible jobs that complete within the service level your team has defined.
Illustrative measurement example
Suppose a workflow processes 1,000 eligible leads and 720 meet the defined success criterion. If attributable processing costs total $180:
- Success rate: 720 ÷ 1,000 = 72%
- Cost per successful lead: $180 ÷ 720 = $0.25
These numbers are illustrative, not industry benchmarks or a claim about expected performance.
Use the baseline to determine whether a new provider, merge rule or workflow change improves results without introducing unacceptable costs or errors.
13. Cost Considerations
The total cost of a lead enrichment workflow includes more than the advertised price of an enrichment API.
Consider:
- Provider charges: Requests, credits, matches or returned fields.
- Verification charges: Email or other contact-verification services.
- Automation platform: Task, execution or subscription costs.
- Infrastructure: Hosting, storage, queues and monitoring.
- Engineering time: Initial implementation, testing and maintenance.
- Operational overhead: Failed-job investigation, manual review and data cleanup.
Reduce unnecessary enrichment costs
- Check internal data before calling external providers.
- Request only the fields you need.
- Skip records that already meet the freshness requirements.
- Cache appropriate results when permitted.
- Use a field-aware provider waterfall.
- Apply retry limits and stop repeated no-match lookups.
- Batch requests when supported and beneficial.
- Track costs by provider and field.
- Review the percentage of paid lookups that produce usable results.
Do not choose the cheapest provider solely by cost per request. A provider that produces more usable matches may have a lower cost per successful enrichment, but that must be demonstrated using representative data.
14. Common Mistakes and Troubleshooting
Mistake 1: Treating every returned value as accurate
Why it fails: A provider can return incomplete, outdated or incorrectly matched information.
Better approach: Validate matches, preserve provenance and route uncertain records for review.
Mistake 2: Creating a new contact before checking the CRM
Why it fails: Repeated events can create duplicate records.
Better approach: Resolve identity first and use stable identifiers, concurrency controls or uniqueness constraints where appropriate.
Mistake 3: Overwriting every existing field
Why it fails: New data may be less trustworthy than the existing CRM value or may overwrite information managed by another process.
Better approach: Define field-specific precedence and refresh policies.
Mistake 4: Retrying every error indefinitely
Why it fails: Permanent errors waste money, increase load and can worsen rate limiting.
Better approach: Classify errors, use bounded retries and move unresolved jobs into a recovery queue.
Mistake 5: Ignoring partial enrichment
Why it fails: A workflow may label useful records as complete failures or may falsely label incomplete records as fully successful.
Better approach: Record field-level outcomes and use explicit completion criteria.
Mistake 6: Sending too much data to every provider
Why it fails: It increases cost and may create unnecessary privacy or security exposure.
Better approach: Minimize request data and retrieve only approved fields.
Mistake 7: Using AI to invent missing contact details
Why it fails: Generated information can look plausible without being true.
Better approach: Use AI for bounded tasks such as categorization or summarization, and verify any output that will be treated as factual.
Mistake 8: Measuring API success instead of business usefulness
Why it fails: Successful HTTP responses do not prove that records are accurate, complete or useful to sales.
Better approach: Measure field completeness, independently assessed accuracy, match quality, processing latency and cost per successful lead.
15. Implementation Checklist
Before building:
- Define the business outcome and eligible lead sources.
- Specify required and optional enrichment fields.
- Identify authoritative sources for each field.
- Confirm provider coverage, API requirements and permitted uses.
- Select the no-code, n8n or coded implementation approach.
- Define duplicate matching and ambiguous-match handling.
- Document field-level merge and freshness rules.
During implementation:
- Normalize and validate incoming records.
- Check for existing records before creating new ones.
- Store credentials securely.
- Validate provider responses and match quality.
- Record field provenance and processing status.
- Implement bounded retries and recovery paths.
- Protect against duplicate writes.
- Restrict logs and access to personal data.
Before production:
- Run tests for normal, partial and failure scenarios.
- Verify CRM updates and deduplication behavior.
- Test timeouts, rate limits and retry exhaustion.
- Establish retention and deletion procedures.
- Set up monitoring and alerts.
- Record baseline accuracy, coverage, latency and cost.
- Start with a limited rollout and review results before scaling.
16. Frequently Asked Questions
What is an automated lead enrichment workflow?
It is a process that automatically retrieves, validates and merges additional information into existing lead records using integrations, APIs and predefined rules. A production-ready workflow also manages duplicates, data provenance, errors and CRM updates.
How do you automate lead enrichment?
Start by defining the required fields and identifying your lead source. Normalize the input, check for existing records, call a suitable enrichment provider, validate the result, merge fields using explicit rules and update the destination system. Add monitoring and recovery paths before scaling.
Can you build a lead enrichment workflow without coding?
Yes. No-code platforms can connect supported lead sources, enrichment services and CRMs. They are well suited to straightforward integrations, although complex matching, field-level conflict resolution and specialized recovery logic may require custom code.
Is n8n suitable for lead enrichment?
n8n can orchestrate triggers, HTTP requests, data transformations, branching and CRM integrations. A self-hosted deployment offers operational control but requires appropriate security, maintenance, monitoring and backup practices.
What is a lead enrichment API?
A lead enrichment API allows an application to request additional information about a contact or company using supported identifiers. The provider returns the fields available for the matched record under its API rules and access conditions.
What is an enrichment waterfall?
An enrichment waterfall calls multiple approved data sources in a defined sequence when previous sources do not return acceptable values. A well-designed waterfall targets specific missing fields and limits unnecessary calls.
Can AI enrich lead data?
AI can help classify job titles, summarize sourced company information or transform text into structured fields. It should not be treated as a reliable source of factual contact information without suitable verification.
How do you prevent duplicate leads?
Use stable record identifiers where available, normalize matching fields, check for existing contacts before creating new ones and protect concurrent writes. Do not rely on names or company domains alone to establish a person's identity.
How do you measure lead enrichment accuracy?
Compare enriched fields against an independent, suitably sampled reference standard. Report the sample size and methodology, and distinguish incorrect matches from missing information.
How much does lead enrichment automation cost?
Costs depend on provider pricing, lookup volume, automation-platform fees, infrastructure, verification services and maintenance. Compare providers using cost per successfully enriched lead, not just cost per request.
How often should lead records be refreshed?
Refresh frequency should depend on the field, its expected rate of change, the business purpose, provider cost and applicable retention requirements. Job titles and company details may warrant different schedules from relatively stable identifiers.
Is automated lead enrichment compliant with data-protection laws?
Compliance depends on the data, jurisdiction, business purpose, source, processing activities and applicable requirements. Review the relevant laws and provider terms, minimize data collection, implement appropriate security and retention controls, and obtain qualified legal advice when necessary.
Conclusion
An automated lead enrichment workflow is most useful when it turns incomplete records into trustworthy, actionable information—not merely when it retrieves more fields.
Start with a clearly defined business requirement, validate inputs, resolve existing records, select providers carefully and establish field-level rules for merging data. Add bounded retries, safe CRM updates, provenance tracking and meaningful monitoring before increasing volume.
Choose the implementation approach that fits your actual requirements. No-code automation is often a sensible starting point, n8n offers a flexible visual approach to API-heavy workflows, and custom code provides greater control when matching, reliability and business logic become more demanding.
If your team needs to connect lead sources, enrichment APIs and CRM systems into a reliable end-to-end process, Causly Lab can help design and implement a workflow tailored to your data model, integrations and operational requirements. The goal is not simply to automate more steps; it is to build a system your team can trust and maintain.