Why Current LLM Workflows Fail Heavy Developers: Token Limits, Context Degradation, and Building Your Own Way Out
As developers push AI assistants into long-running coding sessions and complex projects, token limits, context degradation, and usage restrictions become real bottlenecks. Explore why these workflows break down and how building a custom AI agent runtime can give developers greater control over context, memory, and task execution.
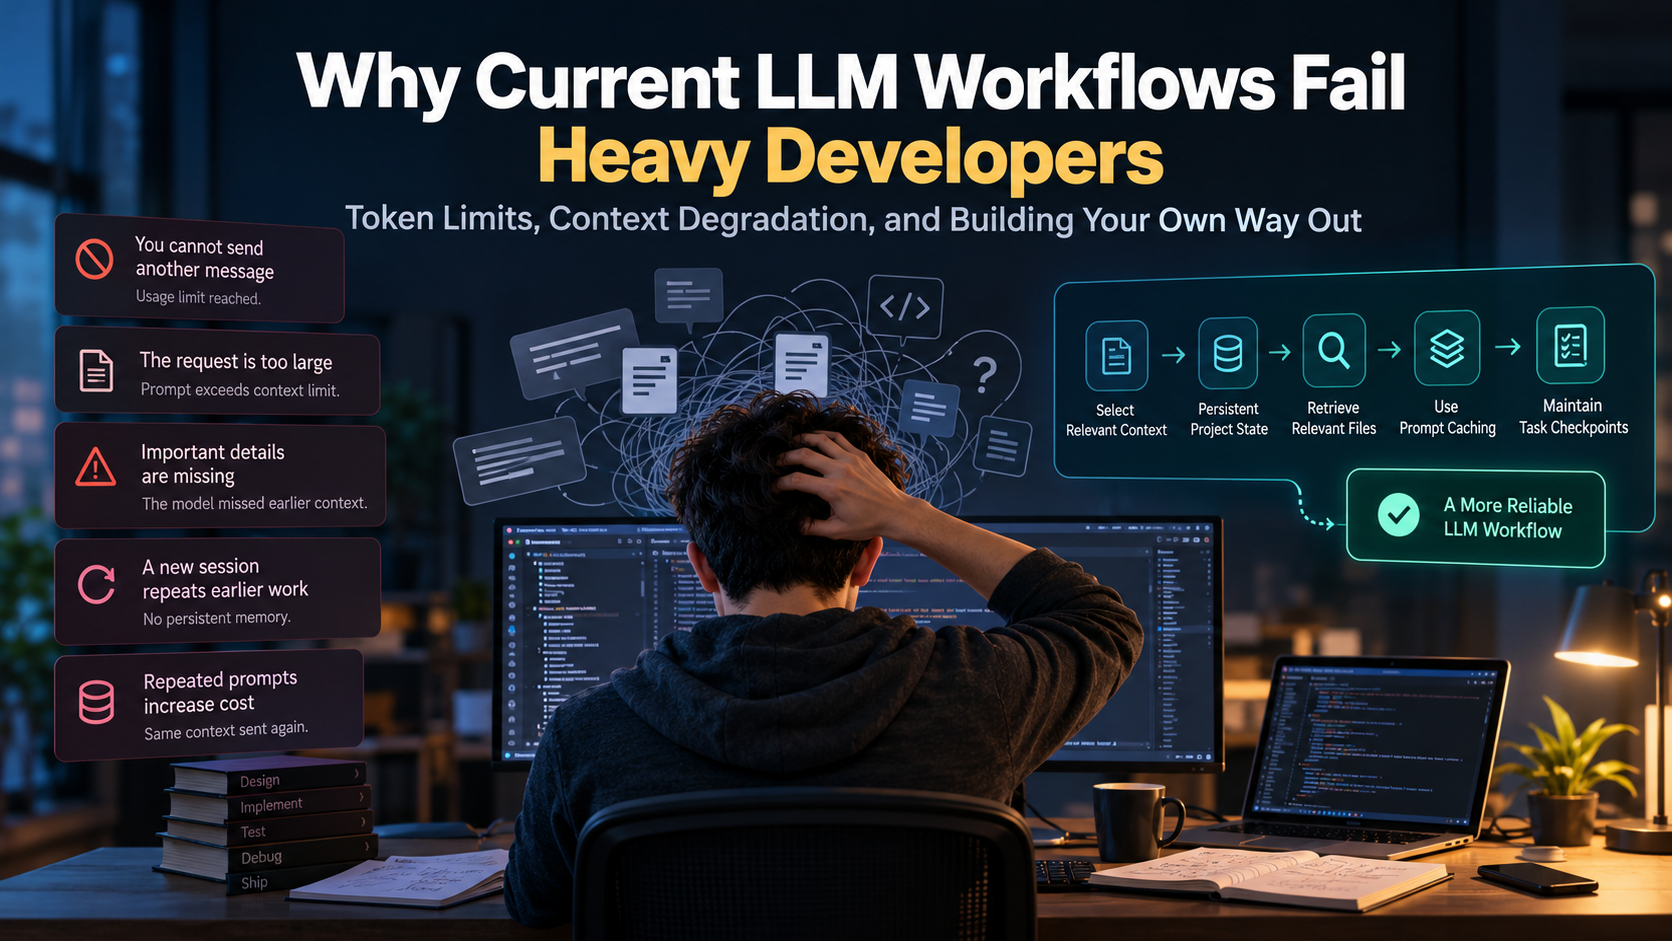
Why Current LLM Workflows Fail Heavy Developers: Token Limits, Context Degradation, and Building Your Own Way Out
AI assistants are useful when a task fits neatly into a conversation. Ask for a function, explain a bug, or request a code review, and a capable model can save considerable time.
The experience changes when AI becomes part of your everyday development workflow.
You might spend an afternoon debugging a production issue, exploring an unfamiliar repository, comparing implementation strategies, and refining a solution across dozens of messages. Then your assistant reaches a usage limit, the conversation grows too large, or a new session starts without the decisions that made the previous one useful.
Suddenly, you're explaining the architecture again, reconstructing earlier decisions, and checking whether the assistant still understands the problem.
These failures often get grouped under the label of context problems. That description is incomplete. Several different limitations can produce similar symptoms, and each requires a different solution.
Some problems come from product-level usage quotas. Others come from model context windows, long-context retrieval failures, repeated input costs, or missing application-level state.
The practical solution is not simply to find a model with a bigger context window. It is to design a workflow that gives the model the right information, preserves important decisions, and can recover cleanly when a session ends.
This article explains the underlying mechanisms, the techniques that address them, and a practical way to evaluate whether a more reliable LLM workflow is worth building.
1. When Your AI Assistant Becomes a Bottleneck
The first step toward fixing an unreliable AI workflow is identifying exactly what is failing.
A developer might experience several distinct problems during a single project, but those problems do not necessarily share the same cause. Usage restrictions interrupt active work Consumer AI products may impose usage quotas, message limits, or other restrictions that vary by product, plan, model, and demand. A long debugging session can run into a limit even when the underlying model could technically process the next message.
For API-based workflows, the constraints are different. Providers can enforce request-per-minute, token-per-minute, daily usage, spending, or other limits depending on the account and model.
These are separate from the model's context window. A developer can have plenty of context capacity remaining and still be unable to send another request.
The distinction matters because a larger context window does not automatically increase your usage allowance. Neither does switching from a consumer interface to an API eliminate all limits. Conversations become harder to use as they grow A long conversation contains more than the information needed for the current task. It may include obsolete implementations, abandoned approaches, repeated explanations, irrelevant debugging output, and decisions that were later reversed.
As the conversation grows, the model has more material to process and more opportunities to overlook the detail that matters.
The problem is not always that the context is full. A model may have room for additional messages but still fail to use an important instruction buried in the existing history. Every new session starts with another explanation Suppose you spent two hours explaining a codebase, identifying a bug, evaluating three possible fixes, and agreeing on a specific implementation.
The next day, you open a new conversation.
Unless the relevant information is carried forward through a saved conversation, persistent memory, project files, or another mechanism, the new session may lack those decisions. You have to reconstruct the working context before making progress.
This is particularly frustrating when the project has accumulated implicit knowledge: why a particular design was selected, which approaches have already failed, or which files must not be changed. The assistant remembers the discussion but loses the objective There is another, subtler failure mode.
The assistant may recall the broad project description but forget the exact acceptance criteria. It may produce plausible code that ignores a constraint, repeat an already rejected approach, or make a change inconsistent with the established architecture.
This is not necessarily a usage-limit problem or a missing-history problem. It can be an instruction-following or reasoning failure.
| Symptom | Likely Cause | First Thing to Investigate |
|---|---|---|
| You cannot send another message | Product quota or API limit | Usage status and provider limits |
| The request is rejected because the prompt is too large | Context or request-size limit | Input size, output budget, and model limits |
| The assistant misses a decision buried in history | Long-context retrieval or instruction-following failure | Context relevance and task-specific tests |
| A new session repeats earlier work | Missing continuity or persistent state | Saved decisions and task checkpoints |
| Repeated prompts increase cost | Repeated input processing | Token usage, prompt caching, and context selection |
These failures call for different interventions. A reliable workflow begins by diagnosing the specific bottleneck instead of treating every frustrating interaction as a memory problem.
2. Token Limits vs. Context Degradation: What's Actually Going Wrong?
Understanding the difference between context limits and context degradation is essential to designing a better AI workflow. What is an LLM context window? An LLM context window is the amount of tokenized input and, depending on the model's accounting rules, output that the model can handle in a single request or generation cycle.
A token is a unit of text or other content processed by the model. It may represent a word, part of a word, punctuation, or another encoded unit. One token is not equivalent to one word.
For a coding assistant, the context can contain:
- System and developer instructions.
- The current user request.
- Earlier conversation messages.
- Code snippets and repository files.
- Tool calls and their results.
- Retrieved documentation and other reference material. The context window is finite. Its exact capacity, output-token budget, and treatment of different content types depend on the model and API.
For example, if a model accepts a maximum of (C) tokens and a request uses (I) input tokens with a maximum output allocation of (O), a simplified planning constraint is: [ I + O \leq C ]
Actual APIs may have additional rules, and some models account for multimodal content or internal reasoning differently. Always check the documentation for the specific model.
The important point is that the available space must accommodate more than the latest user message. The relevant conversation history, instructions, tool definitions, and expected output all compete for capacity.
What happens when you hit a token limit?
A context-window limit is a capacity constraint, not a guarantee that the model has understood everything up to that point.
Depending on the product or application, an oversized request may be rejected, older messages may be truncated, or the application may summarize or compact the conversation before sending it to the model.
These behaviors are implementation-dependent. An application that automatically summarizes history is not necessarily preserving every important detail, and an application that truncates old messages can accidentally remove a critical decision.
A useful first diagnostic is to inspect the actual request sent to the model rather than relying only on the length of the visible conversation.
What is context degradation?
Context degradation is a broader term for a decline in the model's ability to use relevant information effectively as the context or task becomes more demanding.
It is not a single standardized failure mode. It can include difficulty locating a fact in a long input, overlooking an earlier constraint, mixing conflicting instructions, or drawing an incorrect conclusion from too much surrounding information.
A model can experience this problem while staying within its supported context window.
Research helps explain why. In Lost in the Middle: How Language Models Use Long Contexts, Liu and colleagues evaluated models on multi-document question answering and key-value retrieval. They found that, in their tested settings, performance often depended on where relevant information appeared in the input. Information placed in the middle could be harder to use than information near the beginning or end.
The paper does not establish that every current model behaves identically. It demonstrates a more important general lesson: being able to accept a long context and being able to use every part of that context reliably are different capabilities.
Missing information versus unused information
Consider two debugging scenarios.
Scenario A: The information is missing.
You told an assistant that your service uses PostgreSQL, that migrations run through a particular tool, and that a specific database constraint must remain unchanged. You start a fresh session without providing those facts.
The assistant cannot reliably apply information it has not been given or cannot retrieve from an available source.
The solution is to preserve and supply the relevant project state.
Scenario B: The information is present but overlooked.
The same database constraint appears in a 60-message conversation. The assistant has received the entire history, but proposes a migration that violates the constraint.
The problem is no longer simply missing context. The model had access to the information but failed to use it correctly.
A better prompt may explicitly surface the constraint near the current task. Retrieving the relevant migration file, adding an acceptance test, or requiring a verification step may help further.
These solutions are not interchangeable. Saving more history does little for a model that already has the necessary information but fails to reason correctly about it.
Why the distinction matters A useful diagnostic sequence is:
- Availability: Was the relevant information actually included in the request or accessible through a tool?
- Selection: Did the workflow surface the most relevant information for the current task?
- Interpretation: Did the model understand the supplied information correctly?
- Execution: Did the resulting code or action satisfy the requirements?
- Verification: Did a test, tool, or human review confirm the result?
Each stage can fail independently. Better context management primarily improves availability and selection; it cannot guarantee correct interpretation, execution, or verification.
3. Why a Bigger Context Window Isn't a Complete Solution
Increasing context capacity is valuable. It allows models to process larger documents, more code, and longer task histories. But capacity alone does not solve the entire problem. More context can mean more irrelevant information
Imagine debugging an authentication failure in a large application.
The repository contains authentication middleware, database models, billing code, deployment scripts, frontend components, and several outdated implementation notes. Only a fraction of this material is relevant to the current failure.
Sending the entire repository may technically fit within the model's context window, yet still be a worse strategy than supplying the relevant middleware, route handler, configuration, error trace, and tests.
More information is beneficial when it contributes to solving the task. Irrelevant material consumes input capacity, increases processing requirements, and can distract from important constraints.
The LongBench research benchmark evaluates long-context understanding across tasks such as question answering, summarization, and code completion. Its findings show that long-context performance varies across models and tasks, and that retrieval-based context compression can help some models without making them equivalent to stronger long-context systems.
Long-context performance is model- and task-dependent
Context-window size is a capacity specification. It is not a universal measure of effective reasoning quality.
A model may be good at finding a specific identifier in a large document but weaker at synthesizing conflicting decisions across many files. Another model may perform better on multi-step reasoning but cost more or respond more slowly.
Even a model that performs well on one long-context benchmark may behave differently on a real debugging task.
This is why evaluation should use representative workloads rather than assuming that the model with the largest advertised context window will produce the best results. Repeated input creates recurring costs Many API workflows send substantial portions of conversation history or reference material with each request.
If a request includes (I) input tokens and the workflow makes (N) calls, the aggregate input-token volume is approximately: [ T_{\text{input}} = \sum_{i=1}^{N} I_i ]
If the input size remains constant, this simplifies to (N \times I).
For example, repeatedly including the same large architecture document in every request can consume substantial input-token volume over a long session. Actual billing depends on the provider, model, cached-token treatment, and current pricing.
The right response is not necessarily to eliminate history. It is to distinguish information that must be present on every request from information that can be retrieved when needed.
Starting a new chat only solves part of the problem
A new conversation can remove obsolete history and create a cleaner working context. It can also be a sensible way to separate unrelated tasks.
However, starting over without carrying forward the essential information creates another problem: continuity.
The developer must reconstruct the objective, constraints, decisions, relevant files, and current progress. If that process is manual, the time saved by clearing the conversation may be lost to repeated explanations.
A better approach is to create a compact handoff containing the information required to resume the task. The next session starts with a smaller context without discarding the project's useful knowledge.
When a larger context window is worth it
A larger context window is useful when the task genuinely requires broad simultaneous access to information—for example, comparing many documents, analyzing a large log, or tracing dependencies across a repository.
It is less compelling when most of the input is repetitive, irrelevant, or available from a reliable external source.
The practical rule is straightforward: use a larger context window when the task needs more information; use context management when the task needs better-selected information. Many workflows benefit from both.
4. The Technical Approaches That Can Help
There is no single technique that solves every LLM workflow problem. The most effective approach depends on whether the primary bottleneck is missing context, ineffective retrieval, repeated input, interrupted sessions, or model capability.
The following techniques address different parts of the problem and can be combined when necessary.
4.1 Context selection and conversation summarization
Problem addressed: Conversations grow larger than necessary, making it harder to retain a useful working context.
Context selection means supplying information relevant to the current task instead of automatically including every previous message. Summarization compresses an existing conversation into a shorter representation of its important information.
For a software development task, a useful summary might contain:
- The current objective and acceptance criteria.
- Relevant architectural decisions.
- Files already investigated or modified.
- Approaches attempted and why they failed.
- Known constraints and unresolved questions.
- The next concrete action. The goal is not to produce a shorter version of the entire conversation. It is to preserve the information needed to continue the work.
Limitations: Summaries can omit details, misrepresent uncertainty, or preserve decisions that have since become obsolete. A summary is a derived representation, not an authoritative record of the codebase.
For that reason, critical facts should be checked against source files, tests, configuration, or explicitly maintained project records.
When to use it: This is usually the best first intervention for developers who repeatedly work through long conversations. It requires little infrastructure and can be applied manually or automated later.
4.2 Persistent memory and structured project state
Problem addressed: Useful decisions disappear between sessions, forcing developers to reconstruct the same context repeatedly.
Persistent memory stores information outside an individual conversation so it can be retrieved later. But not all information belongs in memory, and not all memory needs to be implemented as an AI-specific feature.
For a software project, a simple directory can provide a reliable starting point:
project/
├── README.md
├── docs/
│   ├── architecture.md
│   ├── decisions.md
│   └── development-notes.md
└── .ai/
    ├── project-context.md
    └── current-task.md
These files serve different purposes:
- architecture.md describes the system's structure and major design choices.
- decisions.md records important decisions and their rationale.
- development-notes.md contains useful findings that may apply across tasks.
- project-context.md provides a concise, reusable overview.
- current-task.md captures the active task, current progress, and next steps. This is an example structure, not a mandatory standard. Existing project documentation can serve the same purpose.
A more sophisticated application might store project state in a database, associate facts with timestamps and sources, or maintain versioned memory records.
Limitations: Persistent memory can become stale. A note that says a module uses one interface may remain unchanged after the interface is refactored. Automatically generated memories can also turn tentative assumptions into apparently authoritative facts.
Store durable decisions separately from temporary task state, record when important information was verified, and treat the current code as the authority for implementation details.
When to use it: Use persistent project state when work spans multiple sessions, multiple tasks, or multiple developers. For a one-off question, it is usually unnecessary.
4.3 Retrieval of relevant files, decisions, and documentation
Problem addressed: The project contains more information than should be sent to the model for every task.
Retrieval allows a workflow to find relevant information when needed.
For example, when investigating a database migration, the application might retrieve:
- The migration file.
- The model definition involved.
- The relevant repository instructions.
- The failing test and error output.
- The architectural decision governing the database schema. The selected material becomes the context for the next model request.
For a codebase, retrieval can start with ordinary tools:
- File-path search.
- Text search using grep or equivalent utilities.
- Repository symbol search.
- Git history and diffs.
- Tests and build output.
- Direct reads of relevant source files. Vector search and embeddings can help when users describe concepts without knowing the relevant filenames. They are not automatically better than direct search. For exact identifiers, error messages, and function names, conventional text search can be simpler and more reliable.
The LongBench paper provides evidence that retrieval-based context compression can improve some long-context tasks, particularly for models that struggle with longer inputs. The benefit depends on the model, task, and quality of the retrieved material.
Limitations: Retrieval can miss relevant information, return outdated documentation, or select several similar but incompatible implementations. A technically accurate document can also be irrelevant to the current task.
A robust workflow should identify the source of retrieved information, prioritize current files, and allow the model to request additional evidence when the initial context is insufficient.
When to use it: Retrieval becomes useful when the project is too large to include in full, or when different tasks require different subsets of project knowledge.
4.4 Prompt caching and reducing repeated input tokens
Problem addressed: Repeated requests contain the same instructions, documentation, or conversation prefix, increasing processing costs and latency.
Prompt caching allows supported providers to reuse computation for matching portions of previous inputs.
For example, an application might repeatedly send:
- Stable system instructions.
- Shared coding standards.
- Tool definitions.
- A common project description.
- The evolving conversation history. If the provider's caching mechanism recognizes a reusable prefix, it may avoid recomputing that portion of the prompt and charge a lower rate for eligible cached input tokens.
OpenAI documents the mechanism and its requirements in its official prompt caching guide. The documentation explains that cache eligibility depends on the model, matching prefix, minimum token requirements, cache lifetime, and request configuration.
The practical implementation principle is to place stable content before changing content when that arrangement is appropriate for the provider's API. Avoid needlessly rewriting the shared prefix on every request.
However, prompt caching is not the same as reducing the context sent to the model. A cached prefix still belongs to the request's context, and cached tokens may still count toward token-based rate limits.
Caching also does not preserve project state in a durable, user-readable form. It reuses computation; it does not replace memory or retrieval.
Limitations: Cache hits are not guaranteed. Changing the prefix, using a different model, exceeding the cache lifetime, or encountering routing differences may reduce reuse. Pricing and cache behavior vary by provider and model.
When to use it: Prompt caching is especially useful for API applications that repeatedly send large, stable instructions or reference material. For an occasional interactive chat, the developer may have little control over the underlying caching implementation.
4.5 Task checkpoints and continuity across interrupted sessions
Problem addressed: A session ends before the work is complete, and the next session lacks a clear record of progress.
A task checkpoint records the state needed to resume work without replaying the entire conversation.
A useful checkpoint includes:
| Field | What to Record |
|---|---|
| Objective | What needs to be accomplished |
| Acceptance criteria | How success will be verified |
| Current state | What has been completed |
| Evidence | Files inspected, tests run, relevant outputs |
| Decisions | Chosen approach and rationale |
| Constraints | What must not change |
| Remaining work | What is unfinished |
| Next action | The immediate step to take |
A checkpoint should distinguish verified facts from hypotheses. For example, "The test fails because the mock returns null" is stronger than the evidence supports if the root cause has not yet been confirmed. In that case, record the observed failure and the suspected explanation separately.
For coding workflows, checkpoints become more reliable when paired with Git commits, diffs, test results, and task-specific documentation.
A checkpoint should not duplicate the entire repository. It should point to the source files and artifacts needed to recover the working state.
Limitations: Checkpoints can become outdated after code changes, and a summary alone cannot guarantee that the next session will interpret the task correctly.
When to use it: Checkpoints are particularly valuable for long debugging sessions, repository migrations, multi-stage implementation tasks, and any work that may be interrupted by a usage limit.
4.6 Model selection and routing
Problem addressed: A workflow uses an expensive or slow model for tasks that do not need its full capabilities—or a weaker model for tasks that require more reasoning.
Different models offer different trade-offs in reasoning quality, context capacity, latency, supported tools, and cost.
A developer can route tasks according to their requirements:
- Use a smaller or faster model for straightforward classification, formatting, or extraction.
- Use a more capable model for difficult debugging, architectural trade-offs, or complex code changes.
- Use deterministic tools for exact operations such as searching files, running tests, and validating schemas. The goal is not to build an elaborate routing system. It is to match the cost and capability of the model to the task.
A simple application might let the user select a model manually. A more mature system could choose one based on task type, previous evaluation results, or an explicit quality threshold.
Limitations: Automatic routing introduces another failure point. A router can underestimate task complexity, choose a model that lacks a required capability, or send a difficult task to a cheaper model that produces unreliable results.
Model switching also does not automatically transfer conversation state, guarantee equivalent outputs, or remove provider limits.
When to use it: Routing is worth considering when an application processes many different task types and model costs or latency materially affect its usefulness. For an individual developer, manual model selection may be enough.
Choosing the Smallest Useful Solution
You do not need all six techniques from day one.
| Your Main Problem | Start With | Add Later If Needed |
|---|---|---|
| Long conversations are hard to manage | Context selection and summaries | Automated retrieval |
| New sessions lose important decisions | Project notes and checkpoints | Structured persistent memory |
| The repository is too large to include | File and symbol search | More advanced retrieval |
| Repeated requests are expensive | Measure token usage and stabilize prompts | Prompt caching |
| Simple tasks consume too much model budget | Manual model selection | Evaluated routing |
| Tasks are repeatedly interrupted | Durable checkpoints | Automated session recovery |
5. How to Design a More Reliable LLM Workflow
A practical design should preserve the project's durable knowledge, provide the current task's relevant context, and recover from interruption without relying on the model to remember everything.
The following architecture can be implemented incrementally. Step 1: Separate project knowledge from task state Project knowledge changes relatively slowly. Task state changes as work progresses.
Keep these concepts separate.
Project knowledge includes architecture, coding conventions, dependency choices, design decisions, and stable constraints.
Task state includes the current objective, files under investigation, attempted fixes, test failures, and remaining steps.
The distinction prevents a temporary debugging hypothesis from becoming a permanent project rule. Step 2: Retrieve only the context needed for the task Start with the task description, repository instructions, and current checkpoint.
Then use tools to find the relevant files and evidence. Do not load every document by default.
For a bug in an API endpoint, the initial context might include the endpoint implementation, its request schema, the failing test, and the relevant error message.
If the evidence points to the database layer, retrieve the related model and query implementation in the next step.
This iterative approach keeps the context focused while allowing the model to request more information as the investigation develops. Step 3: Build a task-specific request The request should clearly distinguish requirements, evidence, and uncertainty.
For example:
Objective: Fix the failing user-registration test.
Acceptance criteria:
- The test passes.
- Existing API behavior remains compatible.
- No unrelated database changes are introduced.
Verified facts:
- The failing test is tests/test_registration.py.
- The error occurs during user creation.
- The current request schema is available in the repository.
Unresolved question:
- Determine whether the failure originates in validation or database persistence.
Instructions:
- Inspect the relevant implementation and test.
- Identify the failure before proposing a fix.
- Make the smallest appropriate change.
- Run the targeted test.
- Report the result and any remaining uncertainty.
This is a request template, not executable code. Its purpose is to make the current task and its verification requirements explicit.
Notice that it does not assume the cause of the bug. It directs the model to investigate before modifying the code. Step 4: Verify changes using tools A model's explanation is not proof that a fix works.
Where appropriate, run:
- Targeted tests.
- Type checks.
- Linters.
- Build commands.
- Relevant integration tests.
- Git diff and status checks. Use the results to decide whether the task is complete or whether more investigation is required.
For a high-impact change, the workflow may also require human approval before merging or deploying. Step 5: Save a checkpoint before ending the session When the task is complete—or when work must stop—update the checkpoint.
A good checkpoint records the actual state rather than the assistant's intended state.
For example:
Current Task: Registration Test Failure
Objective Fix the registration test without changing API behavior.
Completed
- Inspected the request schema and registration handler.
- Identified the validation mismatch.
- Updated the handler to use the expected field.
Verification
- Targeted registration test: passed.
- Full test suite: not run.
Remaining Work
- Run the complete test suite.
- Review the final diff.
Next Action
Run the full test suite, inspect failures, and review the diff before marking the task complete.This example illustrates a possible checkpoint format; it does not report an experiment or an implementation that has actually been tested.
If the task is still unresolved, record what failed, what was learned, and what should be tried next. Do not save an unverified diagnosis as a confirmed fact. Step 6: Resume from the checkpoint, not from the beginning At the next session, read the checkpoint and verify that its assumptions still match the current repository state.
Then retrieve the necessary files and continue from the next action.
This reduces repeated explanation while keeping the model grounded in current evidence.
The workflow can be summarized as follows:
-
Load project state
Read stable project notes and the active task checkpoint. -
Retrieve relevant evidence
Find source files, documentation, tests, and current outputs. -
Ask the model to work
Provide explicit requirements, constraints, and relevant context. -
Verify the result
Run tests and inspect actual tool outputs and changes. -
Save the next checkpoint
Record verified progress, unresolved issues, and the next action.
This architecture is intentionally simple. A developer can begin with Markdown files, repository search, and ordinary model calls. A custom application can automate the same process later without changing its underlying principles.
What should you automate first?
Automate the most repetitive, measurable part of the workflow.
For one developer, that may be generating a session summary. For another, it may be retrieving repository files or saving a checkpoint after every completed task.
Start with a manual workflow, observe where time and context are repeatedly wasted, and automate those steps.
This avoids building a complex AI-agent architecture before establishing that the extra infrastructure is useful.
6. How to Measure Whether Your Solution Actually Works
A workflow that feels more organized is not necessarily more accurate, cheaper, or faster.
Context management should be evaluated against a baseline so you can identify which changes improve the results and which merely add complexity.
Define the Metrics That Matter
| Metric | What It Measures | How to Evaluate It |
|---|---|---|
| Context retention | Whether important facts remain available across sessions | Ask questions about documented decisions and constraints |
| Task completion | Whether the task satisfies its requirements | Run tests or compare against predefined acceptance criteria |
| Instruction-following | Whether the model respects constraints | Check outputs against explicit requirements |
| Input-token usage | How much input the workflow sends | Record provider-reported token counts |
| Latency | How long a task takes | Measure request time and total task duration |
| Cost | What the workflow spends on model calls | Use actual billed token categories and current prices |
| Recovery quality | Whether interrupted work resumes correctly | Compare resumed sessions against a defined task state |
For coding tasks, passing tests is stronger evidence than a model's self-reported confidence. However, tests are only as comprehensive as their coverage, so a passing suite does not prove the absence of every defect.
Similarly, a shorter prompt is not automatically better. If it removes a critical constraint and causes an incorrect implementation, the token savings may be a false economy.
A Reproducible Experiment You Can Run
The following is a proposed experiment, not a completed benchmark. No results are claimed.
Its purpose is to test whether structured context management improves continuity and efficiency for your own development workload.
Experiment Design
Select 20 representative tasks from your normal workflow. Examples include debugging a test, modifying an API endpoint, understanding an unfamiliar module, and implementing a small feature.
For each task, prepare:
- A fixed starting repository state.
- A clear task description.
- Explicit acceptance criteria.
- The project information required to solve it.
- A reproducible verification procedure.
Create two workflow conditions.
Condition A: Conversation-Heavy Baseline
Use your usual approach, including the relevant conversation history and the normal process for resuming work. Record how much context is supplied and what happens when a task is interrupted.
Condition B: Structured-Context Workflow
Use a compact project summary, a task checkpoint, and retrieval of relevant files. Preserve the same underlying project state and acceptance criteria.
Keep the model, model configuration, available tools, and other relevant conditions as consistent as practical. If you also change the model or reasoning settings, record that change rather than attributing all differences to context management.
For tasks that do not naturally span multiple sessions, use a controlled interruption: stop after a predefined stage and resume in a new session.
Run the Experiment
- Define the acceptance criteria before starting.
- Run each task under both conditions.
- Alternate or randomize the order to reduce systematic ordering effects.
- Record the actual input and output token usage, elapsed time, and cost.
- Evaluate the result using the same tests and acceptance criteria.
- Record whether important facts were missed, constraints were violated, or work had to be repeated.
- Repeat enough tasks to distinguish consistent patterns from isolated successes.
Where practical, avoid letting the same model see the first condition's solution before attempting the second. Otherwise, knowledge of the previous result can contaminate the comparison.
Calculate the Results
For successful tasks, calculate the average input-token usage:
[ \overline{T}{\text{input}} = \frac{\sum{i=1}^{n} T_i}{n} ]
Calculate task success rate as:
[ \text{Success rate} = \frac{\text{Tasks passing acceptance criteria}} {\text{Tasks attempted}} \times 100% ]
Measure the total time from task start to verified completion, including retrieval, summarization, recovery, and human intervention. This captures the overhead that request latency alone misses.
For cost, sum the actual charges for uncached input, cached input, output, and any other billable operations relevant to the provider.
A simple comparison table can be filled with your measured results:
| Metric | Baseline | Structured Workflow |
|---|---|---|
| Tasks passing acceptance criteria | Measure | Measure |
| Average input tokens per task | Measure | Measure |
| Average time to verified completion | Measure | Measure |
| Total model cost | Measure | Measure |
| Tasks requiring repeated context setup | Measure | Measure |
| Constraint violations | Measure | Measure |
Do not interpret a difference in averages as proof that one workflow is universally better. With only 20 tasks, results may be sensitive to task selection, model variability, and a few difficult cases. Inspect individual failures and, for larger evaluations, consider confidence intervals and paired statistical comparisons.
Evaluate Prompt Caching Separately
If repeated input tokens are a major cost driver, conduct a second experiment comparing cache-eligible repeated requests with requests that do not reuse the same prefix.
Use the same task, model, and request structure where possible. Record:
- Total input tokens.
- Cached input tokens.
- Cache-write usage, if reported.
- Time to first token.
- Total response latency.
- Actual billed cost.
Repeat requests under realistic intervals because cache lifetime and routing affect whether reuse occurs.
OpenAI's prompt caching documentation describes the usage fields and cache behavior available for its supported APIs.
A successful caching experiment may show reduced cost or latency without changing task accuracy. That is useful, but it does not establish that the workflow has improved context retention.
Measure context quality, task success, efficiency, and continuity separately. They are related outcomes, not interchangeable metrics.
7. Trade-offs, Limitations, and Common Mistakes
Better context management introduces its own engineering costs. The objective is not to eliminate every possible failure; it is to make the workflow more reliable without creating a larger maintenance problem.
Overengineering the Memory System
A developer building a small project does not necessarily need a vector database, a memory service, an orchestration framework, and several background workers.
A README, a concise task checkpoint, and repository search may solve the actual problem.
Add infrastructure when a simpler approach demonstrably fails. Every additional component creates more code to maintain, more failure modes, and potentially more latency.
Treating Memory as Truth
Stored information can be incomplete, stale, or incorrect.
A memory system should distinguish durable decisions from temporary observations and unverified hypotheses. It should also make it possible to update or invalidate records when the project changes.
For implementation details, the current repository and its tests should generally take precedence over an old AI-generated summary.
Retrieving the Wrong Information
Retrieval is only useful if it returns relevant and sufficiently current evidence.
A search system can select a deprecated API example, a similarly named function, or documentation for another version. If the retrieved context is misleading, a model may produce a convincing but incorrect answer.
Use source paths, version information, and relevant code excerpts where possible. Verify important conclusions against the actual implementation.
Assuming Caching Solves Context Limits
Prompt caching can reduce repeated computation and, for eligible models, lower input costs. It does not remove the need to send a valid request, expand the context window, or guarantee that the model will use the supplied information correctly.
A cached request can still be too large, exceed an applicable rate limit, or produce an incorrect answer.
Ignoring API Rate Limits and Billing
A custom application does not automatically bypass provider restrictions.
API limits may include requests per minute, tokens per minute, or other account-specific constraints. Providers can also enforce spending controls and separate limits on particular models or services.
A robust application should inspect provider responses, respect retry guidance, use bounded exponential backoff with jitter where appropriate, and avoid repeatedly retrying permanent failures. Retries should also account for the possibility that a timed-out request may already have been processed.
Prompt caching does not necessarily exempt cached tokens from token-based rate limits. Check the current documentation for the provider and model you use.
Confusing Consumer Quotas with API Limits
Consumer-product quotas and API rate limits are different systems.
A subscription may limit how frequently a user can access a particular model or feature. An API account may instead be constrained by its rate tier, token throughput, billing configuration, or account-level restrictions.
Moving from a consumer interface to an API changes the usage and integration model; it does not guarantee unlimited usage. API access also requires engineering work, usage monitoring, and a budget.
For example, OpenAI's current ChatGPT usage documentation explains that allowances depend on the plan, model, and applicable workspace settings. These product-level limits should not be confused with API rate limits.
Assuming a Custom Workflow Eliminates Model Failures
A custom application can improve context selection, preserve state, and recover from interruptions. It cannot guarantee perfect reasoning, eliminate every long-context failure, or ensure that generated code is correct.
Some tasks remain difficult because the model lacks the necessary capability, the evidence is ambiguous, or the problem requires information that is not available.
The right response is to combine the model with deterministic tools, explicit acceptance criteria, and human review where the consequences justify it.
Adding Latency Without Improving Outcomes
Retrieval, summarization, routing, and checkpoint management all take time.
If a simple question requires a database lookup, two extra model calls, and a multi-stage validation pipeline, the architecture may be solving a problem that does not exist.
Measure the total workflow, including the overhead of managing context. Optimize the parts that have a meaningful effect on quality, cost, or recovery.
When a Normal Chat Interface Is Enough
A standard chat interface remains a good choice for one-off questions, small coding tasks, exploratory research, and work that fits comfortably within a single session.
You may not need a custom workflow if:
- The project has little persistent state.
- Tasks are short and independent.
- The interface already handles context effectively for your use case.
- Usage restrictions rarely affect your work.
- The maintenance cost of a custom system would exceed the benefit.
An existing framework is also a reasonable choice when it already provides the session management, retrieval, or tool integration you need.
Building your own workflow makes sense when you have a concrete, recurring problem that existing tools do not address adequately. It is not inherently better simply because it offers more control.
8. Conclusion: Build for Continuity, Not Just Capacity
LLM workflows become frustrating for heavy developers for several reasons: usage restrictions interrupt work, context windows limit how much information can be processed at once, long-context performance can be unreliable, and new sessions may lose important project decisions.
These are different problems, and they require different solutions.
A larger context window helps when a task genuinely needs more information. Context selection helps reduce irrelevant input. Persistent project state and task checkpoints preserve continuity. Retrieval supplies relevant evidence, while prompt caching can reduce repeated processing costs. Model selection helps balance capability, latency, and expense.
None of these techniques guarantees perfect accuracy. Their value comes from addressing specific weaknesses and verifying that the overall workflow improves.
If you want to get started, keep it simple:
- Document your project's important decisions and constraints.
- Maintain a short checkpoint for the task currently in progress.
- Retrieve relevant files instead of repeatedly supplying the entire conversation or repository.
- Verify generated changes with tests and other appropriate tools.
- Measure context recovery, token usage, task success, latency, and cost before adding more infrastructure.
The broader lesson is that a reliable AI development workflow should not depend entirely on the continued availability of one conversation.
Treat the model as a component of your development system, not as the sole owner of its state. Preserve the information that matters, make evidence available when needed, and ensure that work can resume when a session ends.
Personal note: I'm exploring these challenges while building an AI co-founder, with a focus on making AI-assisted development more reliable across long-running tasks and interrupted sessions.
9. Frequently Asked Questions
Why do LLMs struggle with long conversations?
Long conversations contain more information to process, including irrelevant details, outdated decisions, and competing instructions. A model may also fail to retrieve or apply important information even when it fits within the context window. Performance depends on the model, task, and organization of the input.
Does a larger context window solve context degradation?
No. A larger context window increases the amount of information a model can accept, but it does not guarantee that the model will use every part of that information correctly. Relevant context selection, clear instructions, retrieval, and verification can still be necessary.
How can developers reduce repeated LLM input tokens?
Avoid automatically resending irrelevant conversation history and large documents. Keep a concise project summary, retrieve only the files needed for the current task, and preserve stable prompt prefixes when prompt caching is supported. Measure actual token usage to identify the largest sources of repetition.
Does prompt caching solve context limits?
No. Prompt caching reuses computation for eligible, matching input prefixes. It may reduce processing latency and input costs, but cached content still belongs to the request's context. Caching does not increase the model's context window or guarantee better reasoning.
How can an AI workflow preserve context across sessions?
Store durable project decisions separately from the active task state. Before ending a session, record the objective, completed work, relevant files, verification results, unresolved issues, and next action. When resuming, read the checkpoint and retrieve the current source files before continuing.
Can a custom workflow bypass provider API limits?
No. A custom application does not remove provider-enforced rate limits, account restrictions, context-window limits, or billing requirements. It can use requests more efficiently, cache eligible inputs, queue work, and implement appropriate retries, but it must still operate within the provider's applicable limits.